Testing that doesn’t scale
Manual QA falls behind every sprint, and automated suites break whenever the interface changes.
AI-Driven QA
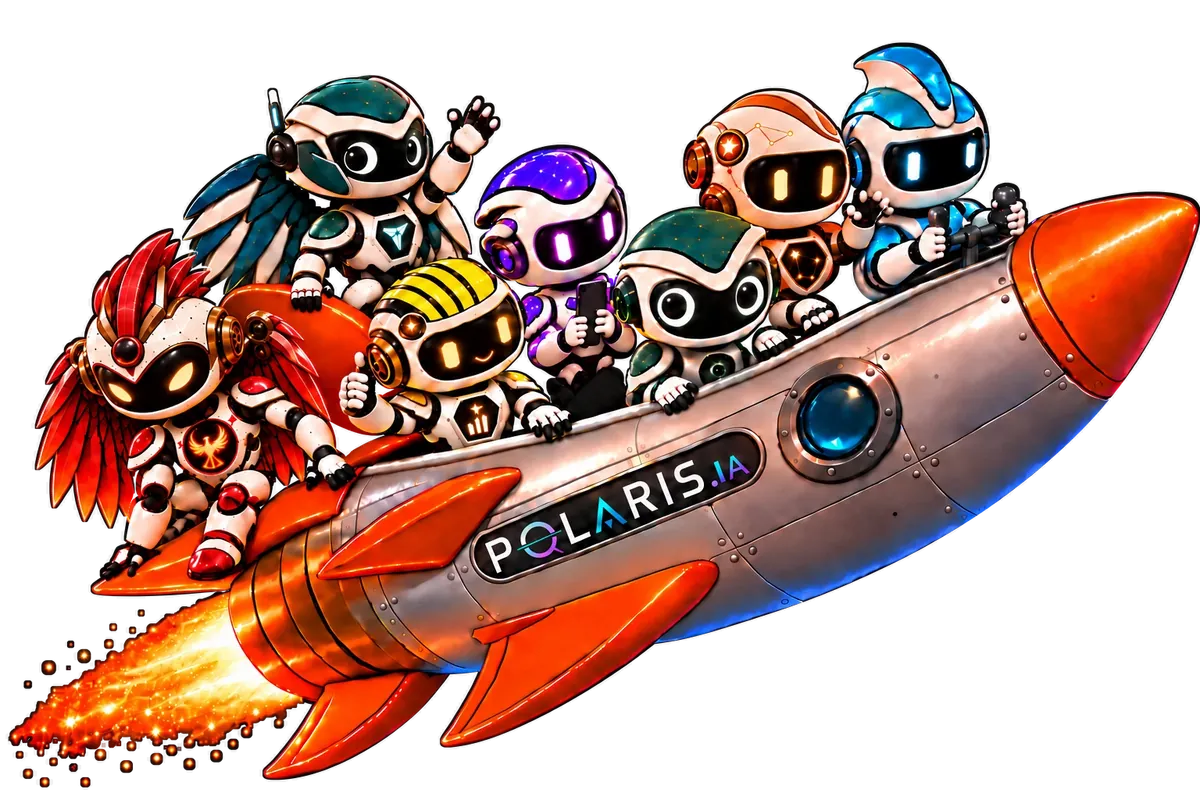
Powered by PolarisOur software quality and security service. We run it on Polaris, a platform of seven specialized agents that test your web app, your mobile app and your APIs, measure their performance and hunt for vulnerabilities. Every conclusion comes with the evidence behind it.
Every release ships faster than the team can test it, and security, functionality and performance get reviewed separately, if at all.
Manual QA falls behind every sprint, and automated suites break whenever the interface changes.
The annual pentest comes too late: between one review and the next, dozens of changes ship that nobody looked at.
A “looks vulnerable” or a “passed” with no trail is useless to the developer who has to fix it.
AI interprets. Engines measure.
In Polaris, the language model helps understand requirements, investigate and explain; actions and measurements are carried out by proven tools like Playwright, k6, Maestro and axe-core. A model’s opinion never replaces a measurement.
Each letter of POLARIS is an agent. Each one gets a goal, works with its own engines and tools, and leaves the results in your project.
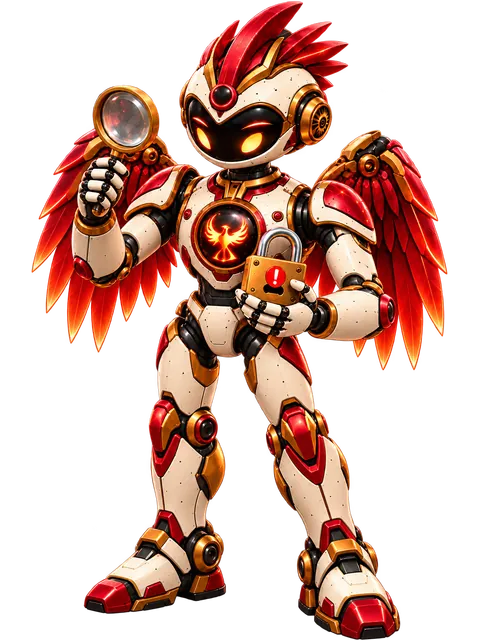
Stay ahead of the attack.
Security with tests and evidence
Assesses web applications and APIs, the code in your repositories, how well your AI agents resist prompt injection and, with authorized access, the real impact after a breach.
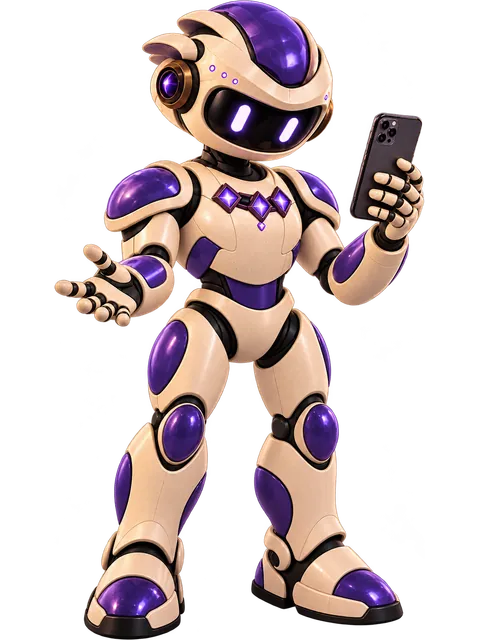
Your app, ready for what’s next.
Journeys and tests in your app
Checks your mobile app’s flows —sign-in, navigation and expected outcomes— on a local Android device or on Maestro Cloud.
Shape your next big idea.
Clear requirements for the team
Drafts user stories, bug reports and test cases, and validates a change against the story that started it.
Every click, more confidence.
Functional testing for your web app
Walks through your web application —public or behind a login— and builds reusable suites to check its flows.
Shine under pressure.
How your service holds up under load
Measures latency, errors and request volume for your endpoints or Postman collections with controlled traffic.
Security that travels with you.
Security inside the app
Analyzes your mobile app package and, when the environment allows it, observes its behavior at runtime.
Every detail counts. So does every person.
An interface you can verify
Audits the visual experience and accessibility of your website, or checks every control against what the code promises.
Every run follows the same path, whichever agent is doing the work.
A URL, an app package, a repository, a user story or a request collection, depending on the agent.
The right agent prepares the work with its engine and specialized tools.
The result is checked against requirements, code, real responses or metrics, not just against what the model claims.
Reports, suites and evidence are saved per project, ready to review and run again.
You know exactly what was tested: which URL, which app version, which repository branch.
A model’s interpretation doesn’t replace a measurement. Every conclusion rests on something that can be verified.
Each agent shows its phases and events as it works, and you can chat with it during the run.
History, reports and evidence per project, so you can review what ran and what’s still pending.
Your team and ours see the same runs, findings and evidence.
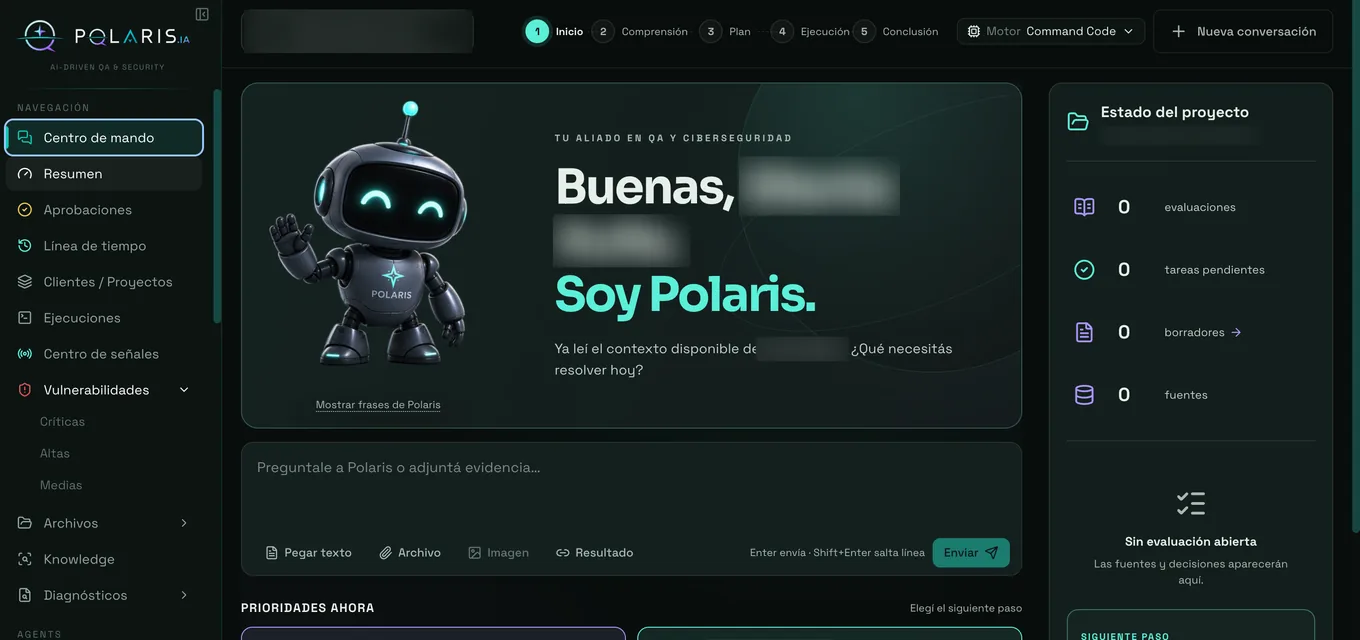
You chat with Polaris, attach evidence and set the next goal. The project status is always in view.
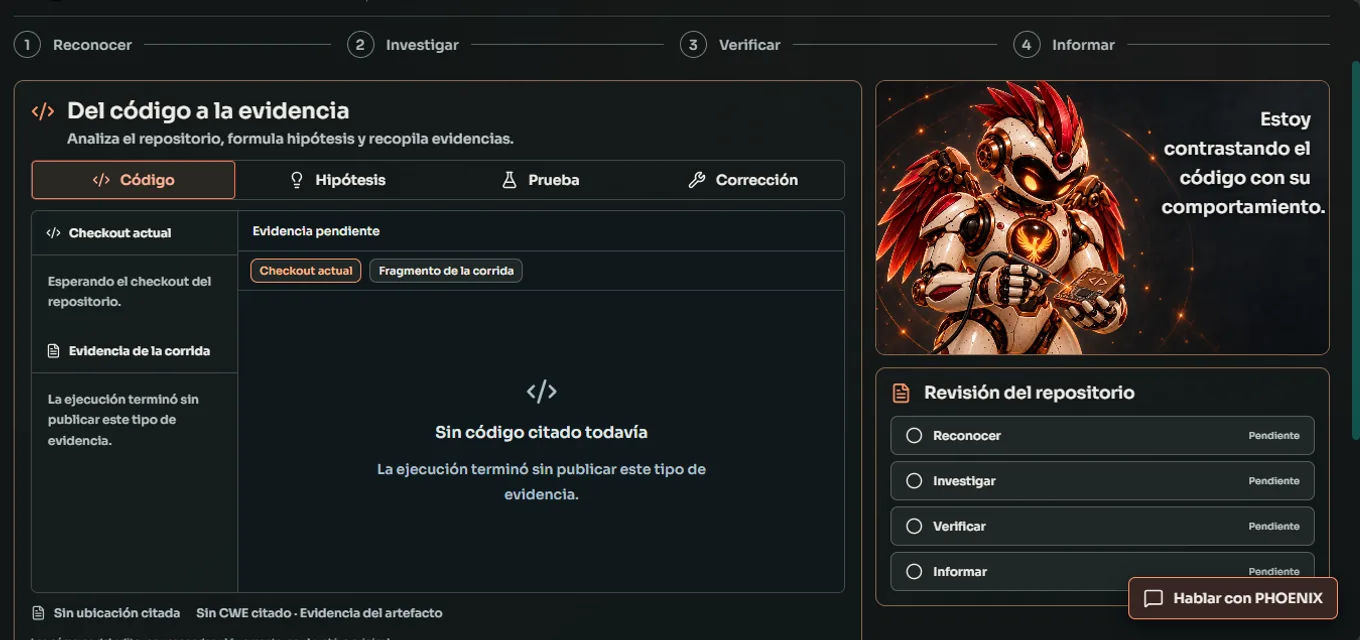
Each agent shows its progress by phase —recon, investigate, verify, report— and you can talk to it while it works.
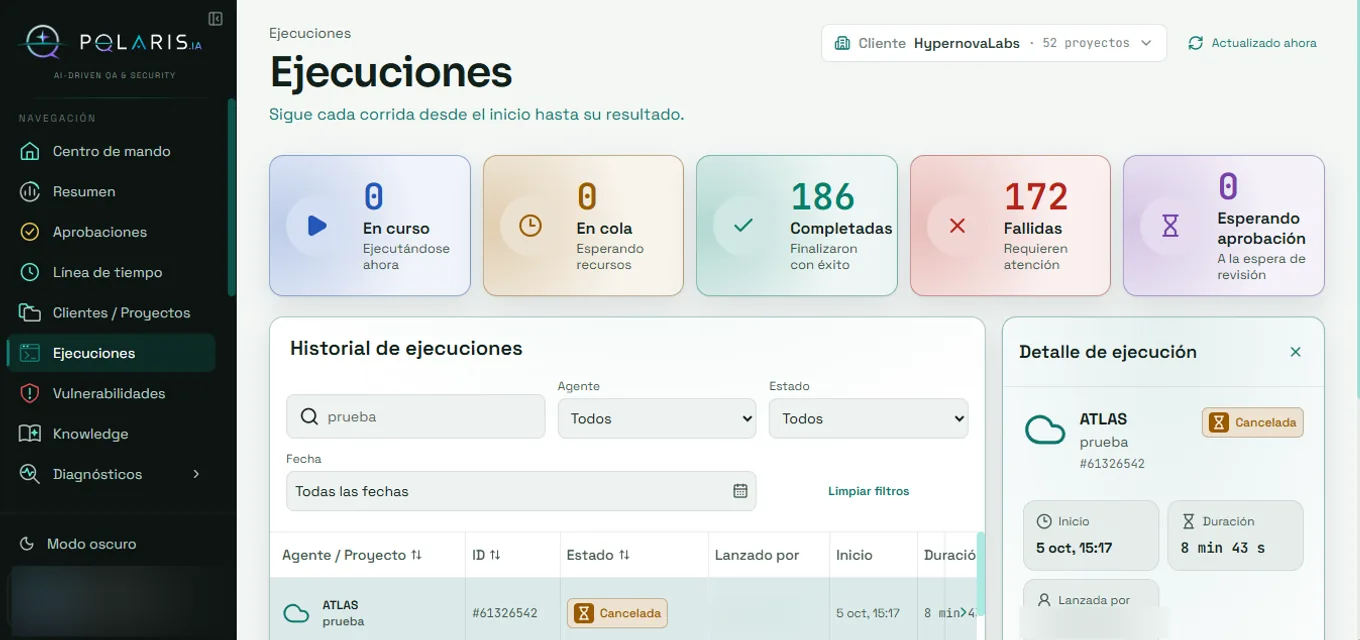
The history of every run with its agent, status, duration and owner.
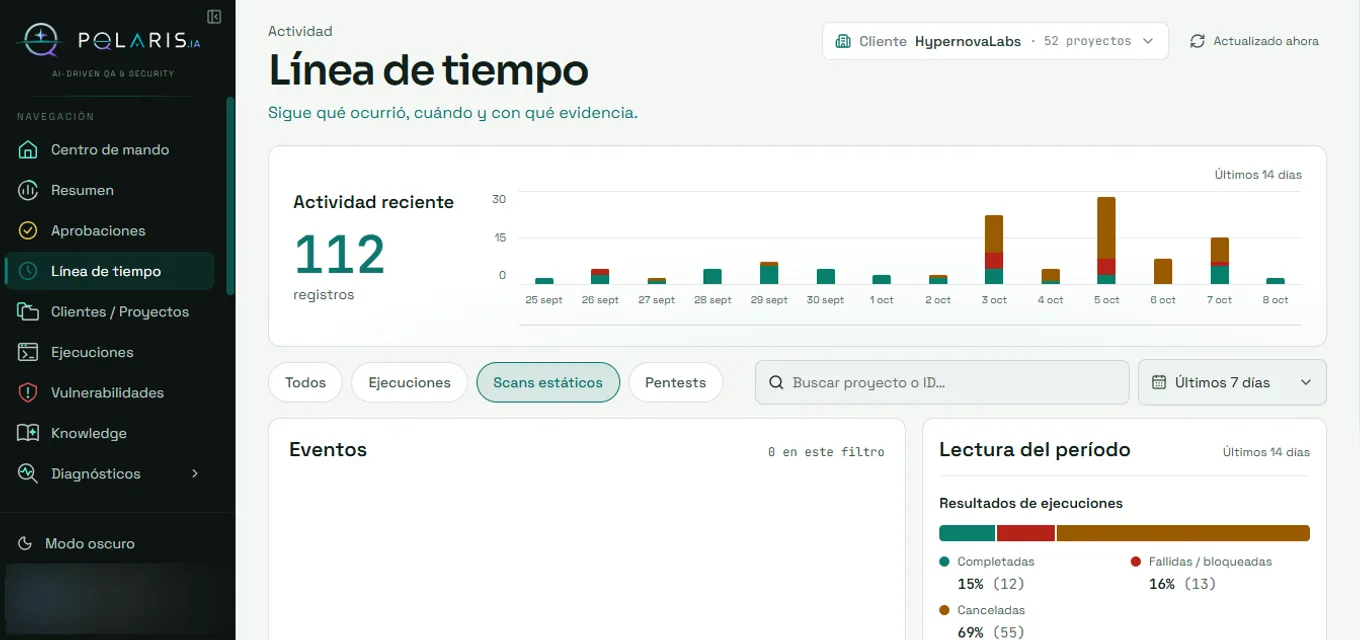
The project’s activity day by day: runs, scans and pentests, with their outcome.
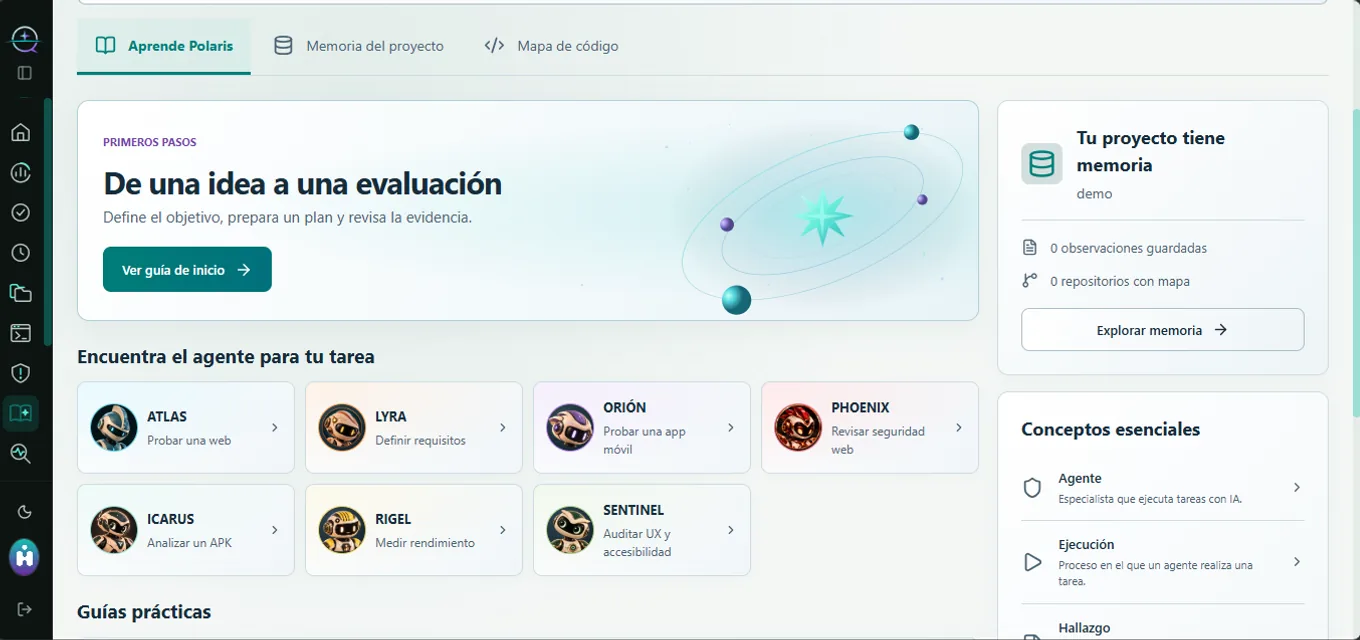
Find the right agent for each task and browse the project memory and its code map.
Platform screenshots with people and project names blurred.
We don’t hand you an opinion: we hand you artifacts your team can review, reuse and run again.
Findings prioritized by severity, with impact, evidence, reproduction steps and a fix recommendation.
Tests and Page Objects that plug into your repository and run in your pipeline.
YAML journeys you can run again with every version of your app.
p95 latency, errors and volume per endpoint against the agreed thresholds.
Acceptance criteria and scenarios ready to review or publish as issues.
Observations with a screenshot, rule and measurement, plus prioritized recommendations.
Our QA and cybersecurity team runs Polaris for you and reviews every result before it reaches your team.
We define assets, environments, test accounts and rules of engagement. Nothing runs without authorization.
We load your URLs, apps, repositories and requirements into Polaris and choose the agents for each front.
The agents run; our specialists validate the findings and rule out false positives.
We present the results to your team and support the fixes until they’re verified.
Suites and tests are ready to run again: every version ships with its own evidence.
No, it multiplies it. Polaris automates the repetitive work and leaves evidence; your team and our specialists decide what gets fixed and when.
Phoenix combines scanning tools with targeted testing and verifies every finding. The report separates what was reproduced with evidence from what remains a hypothesis.
We recommend working on a QA or staging environment with test accounts. Scope and authorization are agreed in writing before anything runs.
They’re used only within the agreed scope and the project in Polaris. If a finding involves secrets, the report documents it without exposing them.
Yes. Playwright suites and Maestro flows are delivered as code and can be published to your repository and your pipeline.
Yes. Phoenix assesses their resistance to direct and indirect prompt injection and to jailbreaks, with references to OWASP LLM Top 10 and MITRE ATLAS.
Icarus analyzes iOS packages statically. Dynamic testing with instrumentation is available today for Android.
Sentinel automates the measurements, but no automated audit is on its own equivalent to a WCAG certification. If you need one, we complement it with specialized human review.